Recent advances in Vision-Language Models (VLMs) have enabled impressive performance on video understanding benchmarks. However, existing evaluations largely focus on short-term reasoning and fail to assess a critical capability: maintaining cumulative temporal consistency over extended time horizons.
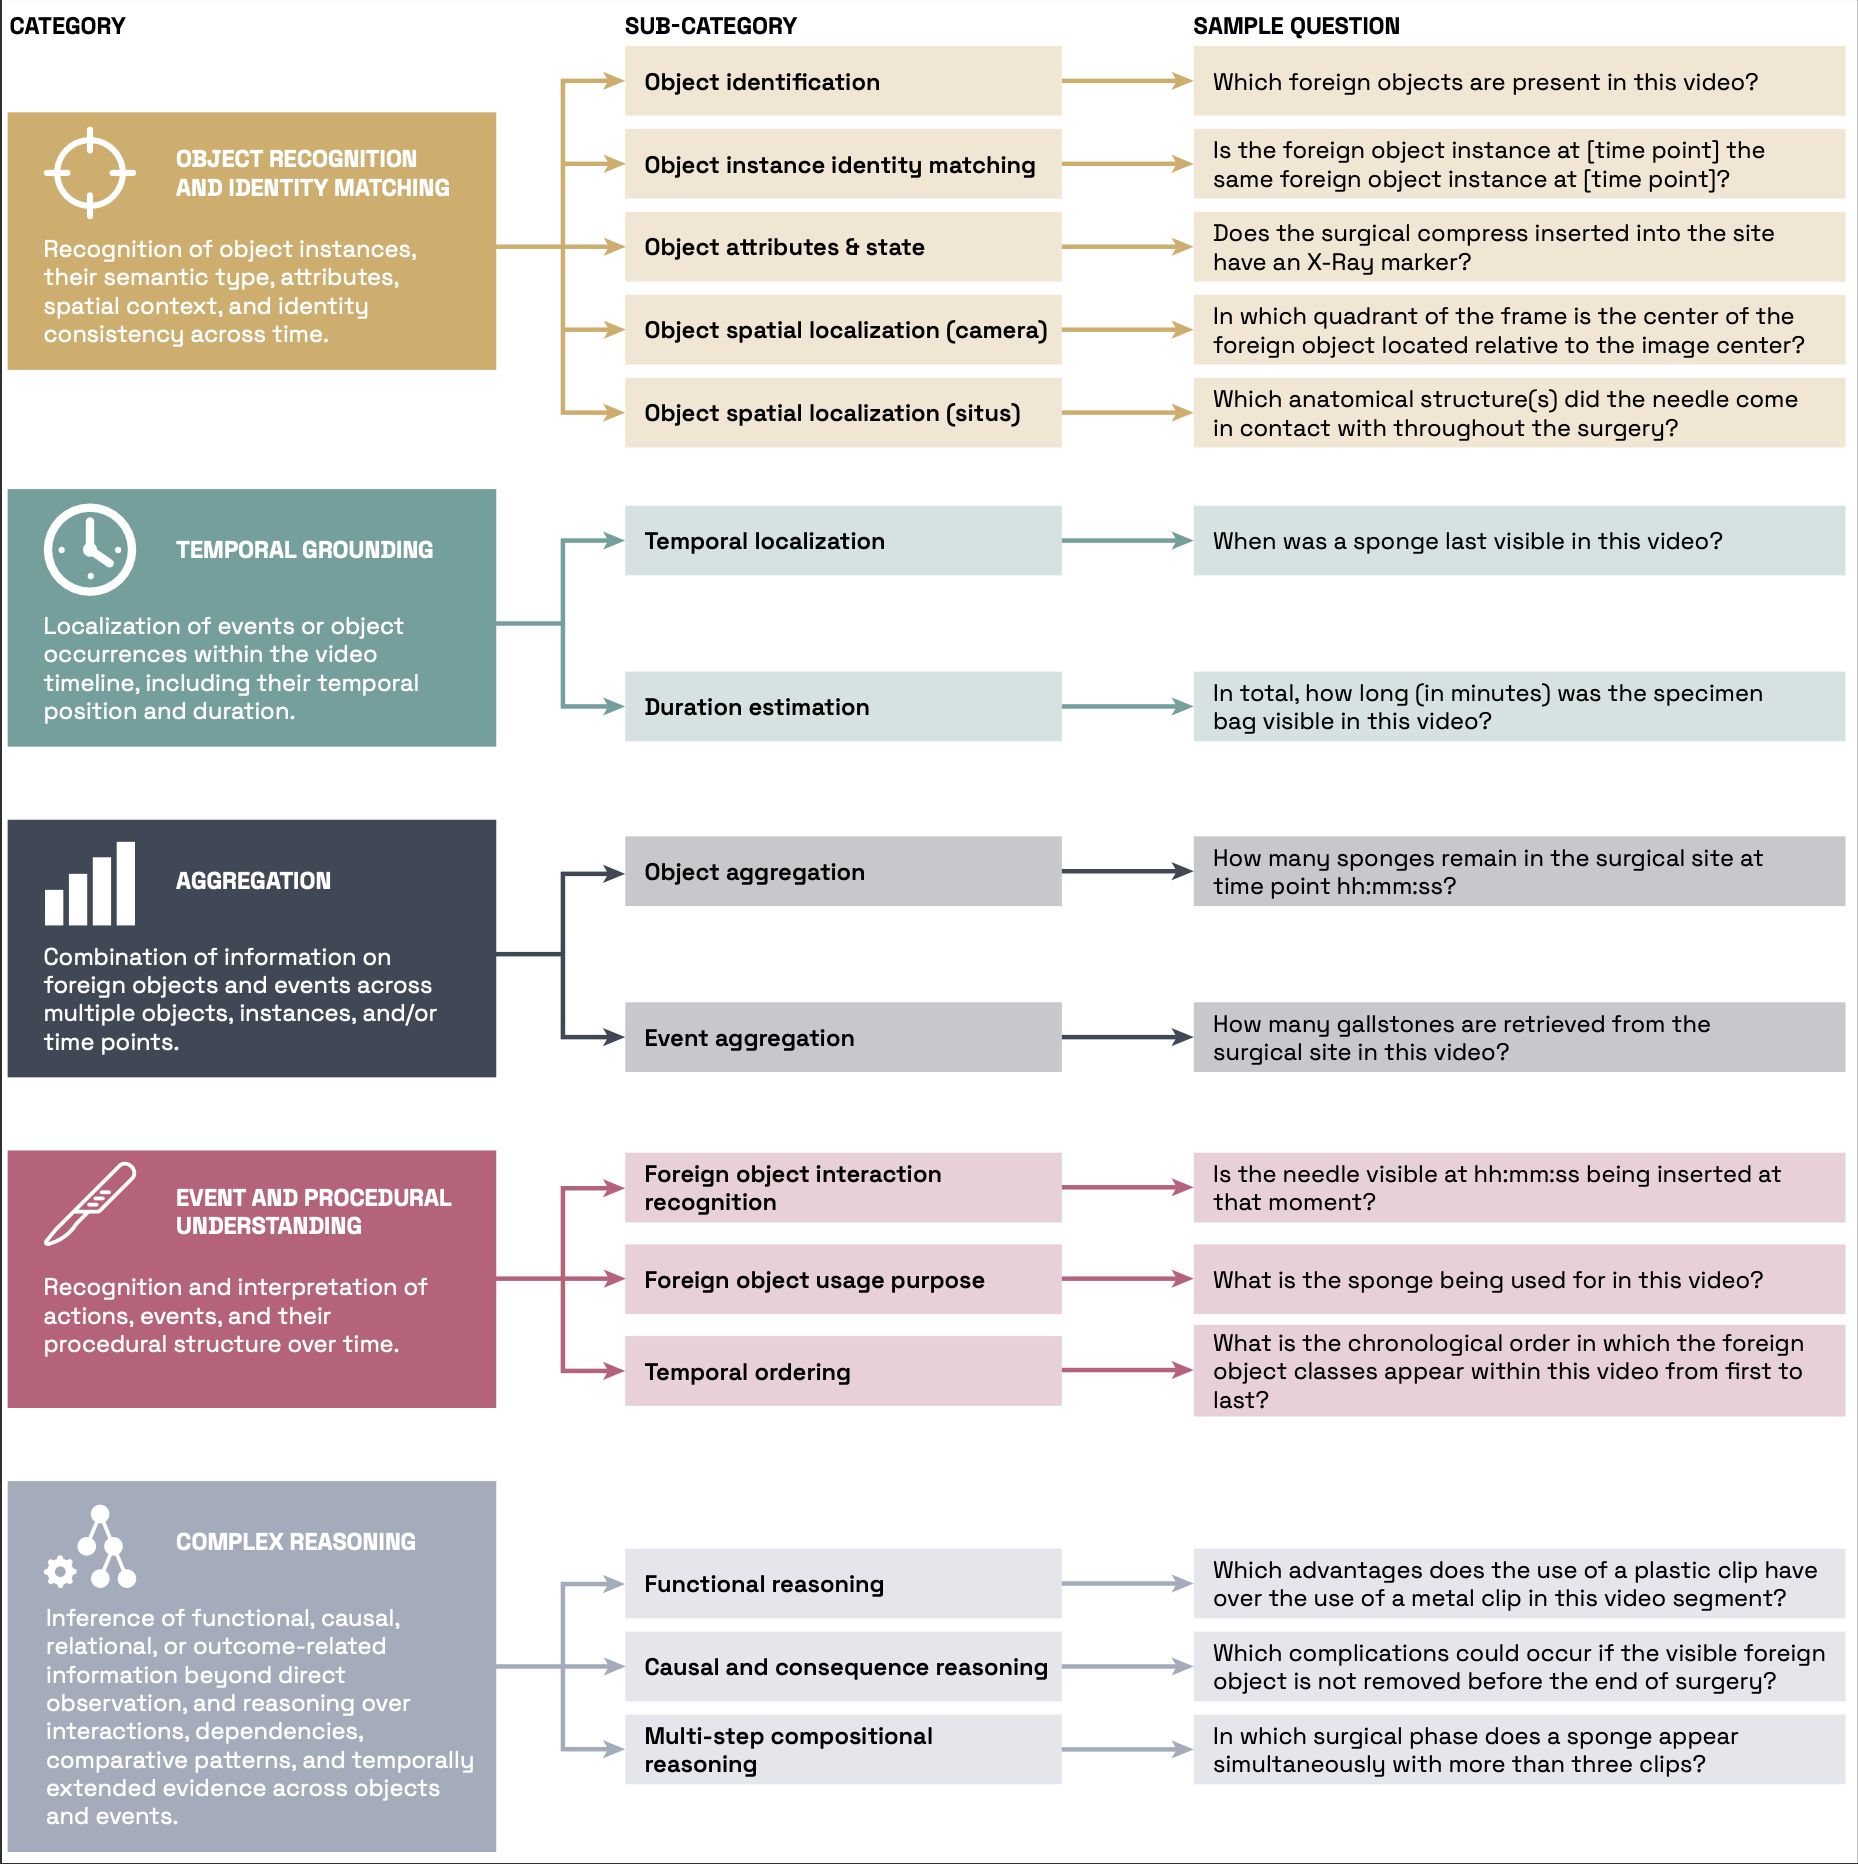
The ORena FOCUS Challenge addresses this gap by providing two clinically grounded datasets designed to benchmark long-context video understanding through the task of Foreign Object Contextual Understanding in Surgery.
Built on full-length colorectal procedures to track foreign objects (e.g., sponges, needles, clips) as they are inserted, manipulated, occluded, and retrieved across operations lasting up to several hours.
Expands the benchmark to laparoscopic cholecystectomies, adopting the identical taxonomy, schema, and multi-track framework as the first batch for standardized comparative evaluation.
| Track | Visual Input | Description |
|---|---|---|
| FRAME | Single frame | Tests short-context perception. No temporal modelling required. |
| SEGMENT | ≤ 5 min clip | Tests understanding of motion and event context within a short window. |
| PROCEDURE | Full video | Tests long-horizon reasoning over complete procedures lasting up to hours. |
huggingface-cli login before loading datasets.
QA annotations can be loaded directly with the standard Hugging Face library:
from datasets import load_dataset

# Load HeiCo-FOCUS
ds_heico = load_dataset("orena-dkfz/heico-focus-vqa", "segment", split="test")
print(ds_heico[0]["question"])   # "How many sponges are visible?"
print(ds_heico[0]["answer"])     # "2"

# Load LapChole-FOCUS
ds_lapchole = load_dataset("orena-dkfz/lapchole-focus-vqa", "segment", split="test")
print(ds_lapchole[0]["question"])
print(ds_lapchole[0]["answer"])orena-focus Python Package
The official utility library provides specialized dataset loaders, answer-format parsing, video managers, and evaluation tools.
→ Visit the orena-focus GitHub Repository
# Installation
pip install orena-focus
Loading Annotations:
from focus import FocusDataset, DatasetSplit, Track

# Load HeiCo or LapChole benchmark
ds = FocusDataset("heico", DatasetSplit.TEST, Track.SEGMENT)
request, reference = ds[0]

print(request.question)        # "How many sponges are visible?"
print(reference.answer)        # "2"
print(reference.format.type)   # "number"
Downloading Video Files for Local Inference:
from focus import FocusConfig, set_config, download

# Set root directory for datasets
set_config(FocusConfig(root_dir="/data/focus"))

# Download video files to local storage
download("heico")     # Downloads into /data/focus/heico/videos/
download("lapchole") # Downloads into /data/focus/lapchole/videos/Citation & Terms: By Challenge rules and the data usage agreement, you are not permitted to share this data beyond members of your team nor use it for external publication or commercial purposes prior to the post-challenge paper release.
Acknowledgements: Developed at the Division of Intelligent Medical Systems (IMSY), German Cancer Research Center (DKFZ), Heidelberg, for the ORena FOCUS Challenge at MICCAI 2026. Partially funded through the Wellcome Leap SAVE program.


